The Queue Is Part of the Agent: Fair Scheduling and Backpressure for Multi-Tenant AI Workloads
When an AI workflow is small, every request can appear to move directly from an API endpoint to a model and then to a tool. Production systems are different. Tenants arrive in bursts. One task may need a short classification call; another may run retrieval, several model turns, browser actions, and a long document export. Retries arrive when downstream services fail. A scheduled batch can collide with interactive traffic.
If every request is admitted and the queue is expected to absorb the difference, the queue becomes the failure mode. Wait time grows without a clear bound, retries multiply the load, and a noisy tenant can make every other tenant slower.
Backpressure is not a performance optimization. It is the mechanism that keeps an overloaded agent platform honest about what it can complete.
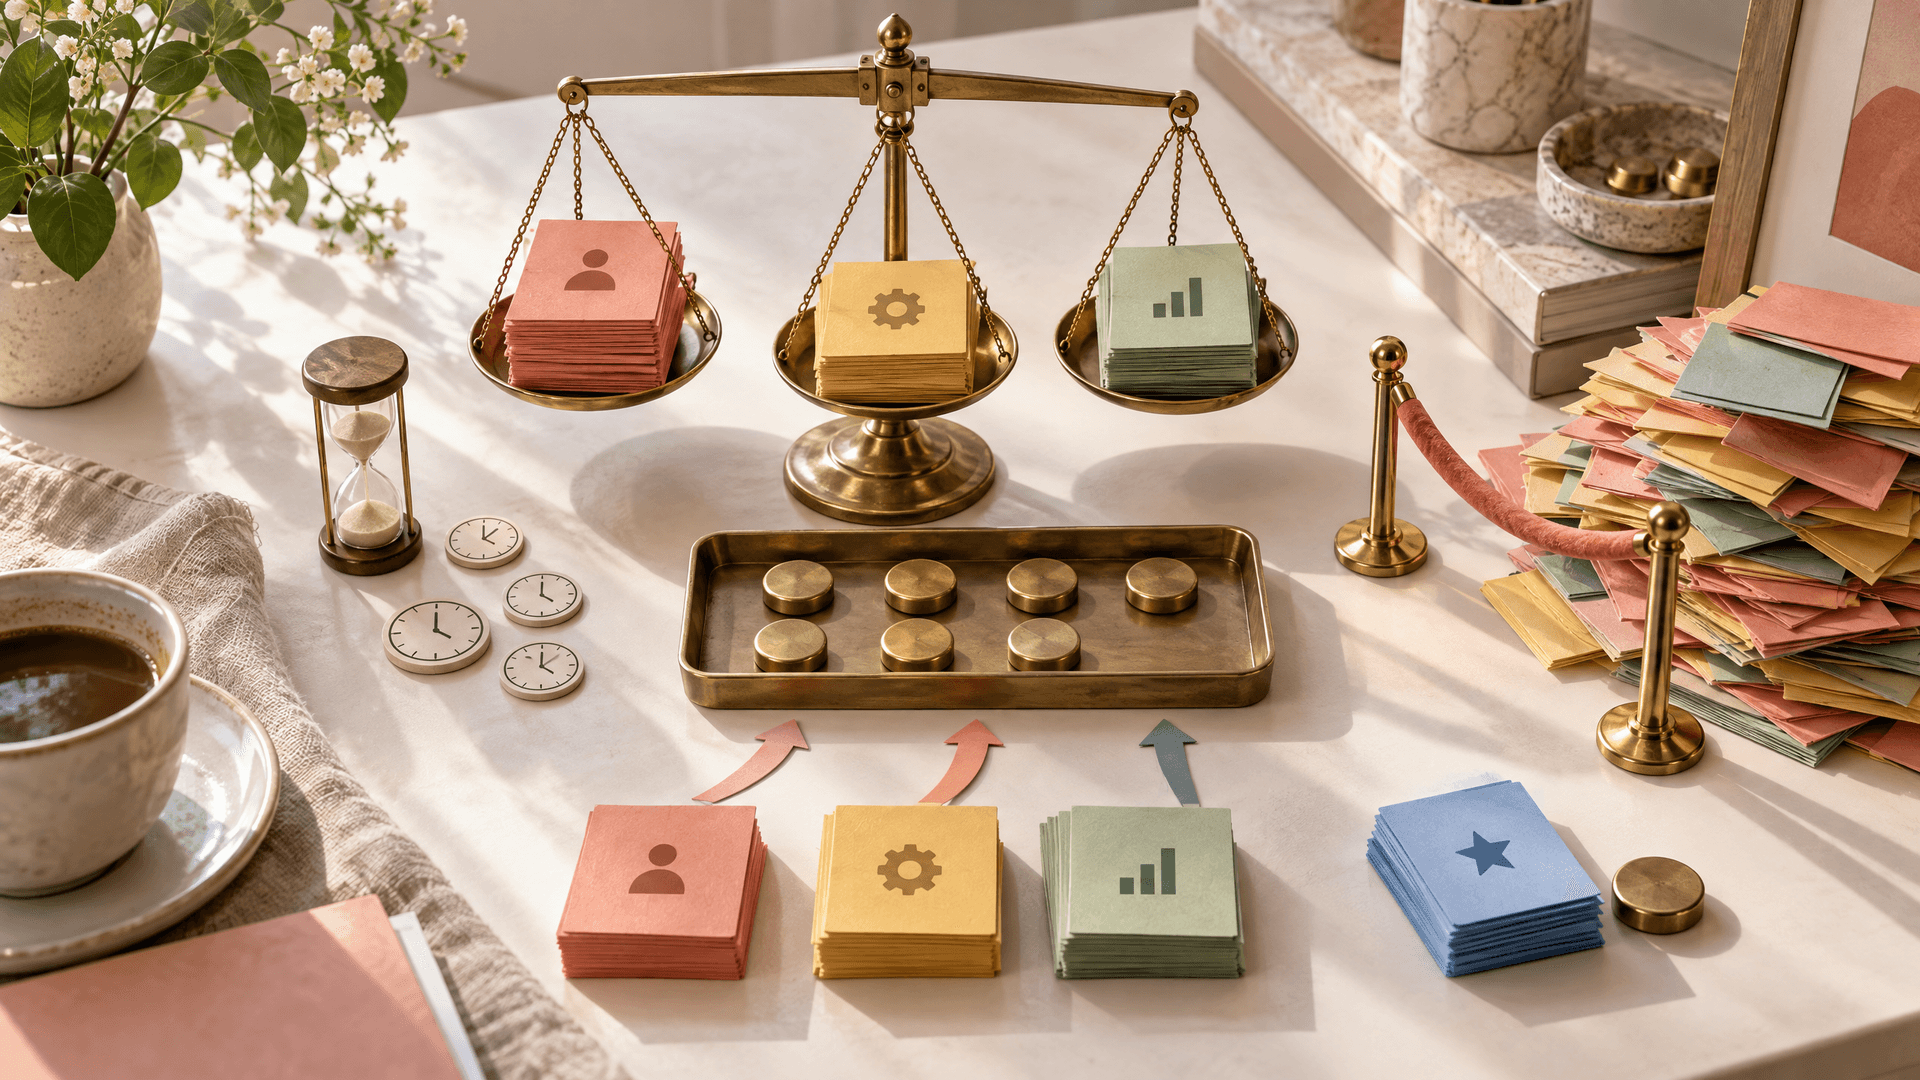
This article presents a production pattern for multi-tenant agent workloads: estimate work before execution, reserve bounded capacity, classify by service class, schedule fairly within each class, reject or defer excess work with a retry signal, and feed actual runtime cost back into future decisions.
Why an agent queue is different from a request queue
A conventional HTTP request often has a relatively narrow cost range. Agent work does not. The resource cost can vary with:
- Input and output tokens.
- Number of model turns.
- Tool-call count and tool duration.
- Retrieval fan-out and document size.
- Browser or code-execution time.
- Model fallback and retry behavior.
- Required deadline and priority.
- GPU memory or context-window pressure.
Counting requests is therefore a poor approximation of work. A 400-token extraction and a 100,000-token research run should not consume the same admission unit.
The current multi-tenant inference research makes this visible. One token-pool experiment modeled entitlement state, output bounds, concurrency, token budgets, and pool contention at the API boundary. With a 16-slot test backend, admission control kept the queue empty and protected guaranteed traffic; without it, the queue grew to 34 requests and latency degraded beyond 19 seconds in the reported overload phase. Those numbers come from a constrained experiment, not a universal promise, but the mechanism is general: reject work before it becomes unbounded waiting. 1
Runtime estimates are also imperfect. The DriftSched study describes “runtime token drift”: actual generation length differs from the estimate used by the scheduler. Its feedback mechanism reduced reported estimation error, while its evaluation showed that scheduler choice changed queue dynamics and tail latency. The study also shows an important trade-off: shortest-job-first can reduce latency, but it does not automatically provide tenant-level fairness. 2
Separate four decisions that are often mixed together
A reliable agent platform should make four different decisions:
- Admission: Can this work start or enter a bounded durable queue now?
- Priority: Which service class should be protected during contention?
- Fairness: How should capacity be shared among tenants inside a class?
- Retry: If work cannot proceed, when may the caller or workflow try again?
A priority system without fairness lets one premium tenant flood the premium lane. Fairness without admission still allows the total backlog to grow forever. Retry without backoff creates a thundering herd during recovery.
Kubernetes API Priority and Fairness is a useful reference architecture. It classifies requests into priority levels with separate concurrency limits, then applies fair queuing within each level. It can queue bursts, reject excess traffic with HTTP 429, and use shuffle sharding so high-intensity flows are less likely to collide with every other flow. It also recognizes that expensive requests may consume multiple “seats,” which is closer to agent workload reality than one-request-one-unit accounting. 3
Mapki micro-card — the four controls
- Admission: Bound total work before execution.
- Priority: Protect interactive or contractual SLO traffic.
- Fairness: Prevent a noisy tenant from monopolizing a shared class.
- Retry: Return a clear, delayed path to recovery instead of immediate repetition.
Model work as a bounded reservation
Start with a conservative admission estimate. It does not need to be perfect; it needs to prevent obviously impossible work from entering the hot path.
A useful reservation can combine token and tool dimensions:
from dataclasses import dataclass
from enum import StrEnum


class ServiceClass(StrEnum):
GUARANTEED = "guaranteed"
STANDARD = "standard"
BATCH = "batch"


@dataclass(frozen=True)
class WorkEstimate:
input_tokens: int
max_output_tokens: int
expected_tool_calls: int
expected_tool_seconds: float
deadline_ms: int
service_class: ServiceClass

@property
def token_budget(self) -> int:
return self.input_tokens + self.max_output_tokens

@property
def work_units(self) -> float:
# Keep dimensions explicit. Tune coefficients using observed data.
token_units = self.token_budget / 1_000
tool_units = self.expected_tool_calls * 0.25
wall_units = self.expected_tool_seconds / 10
return token_units + tool_units + wall_units
The estimate should be stored with the job. At completion, record actual input tokens, output tokens, tool calls, and tool duration. Maintain a bounded moving estimate by tenant, workflow type, and model. Do not allow a caller to claim a tiny max_output_tokens value while the workflow can silently perform ten more model turns.
Admission can then be expressed as a reservation against a pool:
from dataclasses import dataclass


@dataclass
class Pool:
capacity_units: float
reserved_units: float = 0.0

def try_reserve(self, estimate: WorkEstimate) -> bool:
if self.reserved_units + estimate.work_units > self.capacity_units:
return False
self.reserved_units += estimate.work_units
return True

def release(self, estimate: WorkEstimate, actual_units: float) -> None:
self.reserved_units = max(0.0, self.reserved_units - estimate.work_units)
# Actual cost feeds the estimator; it does not retroactively break safety.
record_runtime_cost(estimate, actual_units)
In a distributed deployment, this reservation must be atomic. Use a transactional store, a strongly consistent quota service, or a single-owner allocator. A local counter in each API replica will oversubscribe the pool during a burst.
Use bounded queues, not infinite hope
A queue should have a defined maximum by service class and tenant. When the queue is full, the API should return a meaningful response:
202 Acceptedwith a durable job ID when the job is safely persisted.429 Too Many Requestswhen the caller should retry after backoff.503 Service Unavailablewhen the capacity pool is temporarily unavailable.- A product-level “deferred” state when the workflow will resume later.
Return Retry-After when the client can retry. The delay should include jitter so thousands of clients do not wake at the same instant.
import random


def retry_after_seconds(
attempt: int,
base: float = 2.0,
cap: float = 120.0,
) -> int:
exponential = min(cap, base * (2 ** min(attempt, 8)))
return max(1, int(random.uniform(exponential * 0.7, exponential * 1.3)))


def admission_response(attempt: int) -> dict:
delay = retry_after_seconds(attempt)
return {
"status": 429,
"headers": {
"Retry-After": str(delay),
"Cache-Control": "no-store",
},
"body": {
"error": "capacity_contended",
"retry_after_seconds": delay,
"message": "Work was not admitted; retry with backoff.",
},
}
Do not retry an admission rejection immediately inside the same request handler. That only turns one request into a loop. Do not let an agent decide that a 429 is evidence that it should call the endpoint faster. The retry policy belongs to the workflow runtime and should be bounded by an attempt budget and a deadline.
Give service classes separate capacity
Interactive work and batch work should not share one undifferentiated concurrency number. A useful first configuration is:
pools:
agent-shared:
capacity_units: 100
classes:
guaranteed:
nominal_share: 0.50
min_units: 30
max_queue: 200
response_when_full: reject
standard:
nominal_share: 0.35
min_units: 20
max_queue: 500
response_when_full: defer
batch:
nominal_share: 0.15
min_units: 5
max_queue: 1000
response_when_full: defer

retry:
max_attempts: 6
base_seconds: 2
max_seconds: 120
jitter: full

estimation:
max_reservation_units: 40
update_window: 500
safety_multiplier: 1.25
The exact numbers are workload-specific. The important properties are visible: guaranteed work has a protected floor, batch work cannot consume all capacity, and every queue has a limit.
Kubernetes APF allows priority levels to lend and borrow capacity within configured bounds. That is a practical pattern for agent platforms too. If interactive traffic is quiet, batch can borrow spare units. When interactive demand returns, borrowed capacity is reclaimed. The bounds prevent the “borrow” behavior from becoming silent starvation. 3
Add weighted fairness inside each class
Priority answers which class goes first. It does not answer which tenant goes first within the class.
Suppose three standard tenants have weights 5, 3, and 2. When all three have backlog, a weighted fair scheduler should aim for an approximate 50/30/20 share of dispatch opportunities. When one tenant is idle, the others may use the available capacity. This is better than a rigid per-tenant partition because it preserves utilization while preventing a busy tenant from dominating a busy period.
Temporal’s Fairness pattern uses a fairness key and optional weight for this purpose. It describes weighted dispatch within a shared Task Queue and explicitly warns that fairness is about dispatch, not task duration or hard compute isolation. That distinction matters for agents: a tenant with 50% of dispatches can still consume more worker time if its tasks are much longer. 4
A simplified weighted scheduler can use deficit accounting:
from dataclasses import dataclass, field
from collections import deque


@dataclass
class TenantLane:
tenant_id: str
weight: int
queue: deque = field(default_factory=deque)
deficit: float = 0.0


def choose_next(lanes: list[TenantLane], quantum: float = 1.0):
active = [lane for lane in lanes if lane.queue]
if not active:
return None

for lane in active:
lane.deficit += lane.weight * quantum

# Work-aware dispatch: choose a lane whose credit covers its head job.
candidates = [
lane for lane in active
if lane.deficit >= lane.queue[0].work_units
]
if not candidates:
# Age all active lanes; do not let a large job permanently block progress.
return min(active, key=lambda lane: lane.deficit)

lane = max(candidates, key=lambda item: item.deficit)
job = lane.queue.popleft()
lane.deficit -= job.work_units
return job
Production schedulers need more detail: aging to prevent starvation, a maximum job width, cancellation, durable state, and protection against a job with an extreme estimate. Still, the key design choice is present: consume fairness credit based on estimated work rather than simply popping one request per tenant.
Mapki micro-card — fairness is not isolation
- Weighted fairness: Proportional dispatch among active tenants.
- Rate limit: Maximum throughput for a tenant or downstream dependency.
- Concurrency limit: Maximum in-flight work.
- Dedicated pool: Hard compute or data isolation.
- Priority: Ordering across service classes.
Use dedicated queues and worker pools when a tenant has a contractual isolation requirement. Use weighted fairness when the goal is shared capacity with proportional progress.
Make retries participate in scheduling
A retry is new demand. It must pass through admission again, carry its original tenant and service class, and consume an attempt budget. Otherwise, a failed downstream dependency can produce a retry storm that bypasses the fairness policy.
Use a retry envelope that preserves identity:
{
"job_id": "job_01JZAGENT42",
"tenant_id": "tenant_acme",
"workflow": "contract_review",
"service_class": "standard",
"attempt": 3,
"max_attempts": 6,
"not_before": "2026-10-22T09:15:32Z",
"deadline": "2026-10-22T10:00:00Z",
"estimated_work_units": 8.4,
"idempotency_key": "contract_review:doc_884:extract:v2"
}
The scheduler should not let a retry jump ahead of fresh interactive work merely because it is old. Give retries an age signal, but keep the service-class boundary and the deadline visible. If the deadline cannot be met, mark the job expired and stop spending capacity on it.
Use durable delivery semantics deliberately
A queue is not durable merely because it has a message broker. You need to define when ownership changes.
Redis Streams consumer groups provide a useful primitive: consumers receive different entries, acknowledgements mark successful processing, pending entries remain associated with consumers, and another consumer can explicitly claim entries from a failed consumer. XPENDING exposes the pending count and ownership so recovery can be monitored. 5
The safe sequence for a tool-using agent is:
1. Read a job and mark it in-flight.
2. Persist a lease or ownership record with an expiry.
3. Execute the step with an idempotency key.
4. Persist the result or durable next state.
5. Acknowledge the queue entry only after the state transition succeeds.
6. Reclaim expired leases and retry through admission.
Never acknowledge before the external side effect is safely recorded. Never retry an unbounded side effect without an idempotency key.
Temporal’s Task Queue model uses a different implementation, but the operational idea is similar: workers poll when they have spare capacity, tasks can persist in queues, and server-side throttling can limit activity dispatch. 6 A durable workflow engine or Redis-based design can both work; what matters is explicit ownership, bounded concurrency, and recovery semantics.
Measure queue wait as a first-class SLO
Model execution time is only one part of agent latency. Emit at least these measurements:
- Admission decision and rejection reason.
- Queue wait duration by tenant and service class.
- Estimated versus actual token and tool cost.
- In-flight work and reserved capacity.
- Dispatch share by fairness key.
- Retry count and retry delay.
- Lease age and reclaim count.
- Model execution time and tool execution time.
- Deadline misses and expired jobs.
- Queue depth at each boundary.
A healthy dashboard should make it possible to answer: “Did this workflow wait because the model was slow, because its tenant was over quota, because another class borrowed capacity, or because a retry storm filled the queue?”
Do not optimize only for average utilization. A pool at 99% utilization with unbounded queue wait is not healthy. Maintain headroom for variance, cancellation, and recovery. Use separate metrics for admitted, running, deferred, rejected, expired, and completed work.
A production rollout sequence
- Inventory work dimensions. Capture tokens, tool calls, expected duration, deadline, tenant, class, and side-effect risk.
- Add an admission gateway. Reject or defer before model and tool workers when reservations cannot fit.
- Bound every queue. Set maximum depth, maximum work width, lease time, and deadline behavior.
- Create service classes. Protect interactive or contractual SLO work from batch traffic.
- Add tenant fairness. Use stable tenant keys and weighted dispatch inside each priority class.
- Keep retries in the same policy. Preserve tenant, class, deadline, and idempotency identity.
- Feed back actual cost. Update estimates from observed tokens, tool duration, and retry behavior.
- Reserve recovery capacity. Prevent a successful recovery from becoming a retry stampede.
- Test noisy neighbors. Flood one tenant and verify that other tenants continue to make progress.
- Test long jobs. Confirm that one large workflow cannot block a lane indefinitely.
- Test fairness under changing demand. Add and remove tenants while measuring dispatch shares and queue wait.
- Define hard isolation separately. Use dedicated worker pools when fairness is not sufficient.
The queue is part of the agent’s behavior. It decides which work gets a chance to run, how long users wait, whether retries amplify outages, and whether one tenant can impose its workload on everyone else.
A production agent platform should therefore make overload visible and bounded. Admit what can fit. Protect the work that has a real deadline. Share the remaining capacity fairly. Retry through the same gate. Record the difference between estimated and actual work. When capacity is scarce, graceful refusal is better engineering than an infinite promise.
References & Community Insights
Production checklist
- Admission estimates token, tool, duration, deadline, tenant, and service class.
- Reservations are atomic across API replicas.
- Every queue has a maximum depth and maximum work width.
- Interactive, standard, and batch classes have explicit capacity behavior.
- Priority and fairness are implemented as separate controls.
- Weighted dispatch uses stable tenant keys and work-aware accounting.
- 429 and deferred responses include retry guidance.
- Retries preserve tenant identity, deadlines, attempt budgets, and idempotency keys.
- Actual runtime cost updates future estimates.
- Queue wait, execution time, and retry time are measured separately.
- Lease expiry and stale-work reclamation are tested.
- A noisy-neighbor test proves that independent tenants continue to make progress.
- Dedicated pools exist for workloads requiring hard isolation.
Want to implement this in your business?
Mapki designs bespoke AI agents, custom workflow automations, and tool-agnostic integrations tailored specifically to your existing ERP, CRM, and databases.